An AI-generated conclusion can continue to influence business decisions even after the original error has been corrected. Shreshta Shyamsundar and Chidambaram GS use a supplier-qualification example to show why correcting the data alone is not enough: companies also need to track the decisions that relied on it.
Manufacturers qualify suppliers before entrusting them with critical work. For regulated products such as medical devices, they collect quality certificates, test reports, insurance documents and regulatory approvals. An AI agent increasingly reviews that evidence first and proposes a finding; a business workflow then decides whether to accept it. The approval enters the supplier-management system, where sourcing processes, readiness dashboards and program reports subsequently rely on it.
Correcting the record does not correct the decision
In the authors' example, an agent finds a mandatory quality certificate valid, the workflow marks the supplier compliant, and the procurement lead approves it for an upcoming order. A few days later, a human reviewer discovers that the certificate does not cover the part being sourced: the agent misread its scope.
At 11:00 a.m., the reviewer corrects the supplier record and sends the case back for review. At 2:00 p.m., however, the readiness dashboard and program report still show the supplier as approved. The sourcing decision remains in force, and the decision-maker receives no notice that its supporting evidence has changed.
A similar problem could arise if a certificate is revoked, expires before shipment, applies to a different plant or proves to be forged. In the example, no individual system necessarily malfunctioned: each processed information that appeared valid under its own rules. The combined result was nevertheless wrong because the company corrected the value, but not its influence.
Reconciling differences between systems is a longstanding enterprise problem. AI agents make it harder by producing conclusions that may combine several sources, appear in different wording and later be retrieved as independent evidence. Reconciling values alone cannot show that differently worded records share an origin or identify the decisions that relied on them.
The issue extends beyond manufacturing. A fraud classification may enter a case record, a risk assessment a management report, and an incident diagnosis a knowledge base. Accepted findings can also become labeled examples, evaluation sets or fine-tuning data. If an incorrect finding survives there, a later model may learn from it as fact.
When repetition looks like evidence
An agent's response begins as a generated assertion. It receives business authority only when an appropriate workflow accepts it for a defined purpose. In a supplier master record, the same assertion may look like an established fact; a dashboard may simply show an approved status without revealing incomplete or pending checks. Reports and search indexes can compress or split the finding further.
That makes the producer of a result a separate question from what the result may be used for. An AI proposal might be sufficient to move a supplier up a review queue but not to approve it or release a payment. The distinction depends on the importance of the decision and the controls governing it.
Propagation can also create the appearance of independent corroboration. A later agent may retrieve the supplier record and a program report as two documents, even though both rely on the same original finding. Different wording can obscure their common origin. A stronger model or relevance-based reranking cannot reliably restore provenance that was lost before the documents reached it. Agent memory and multi-agent workflows can further increase the risk of assertions reinforcing themselves.
Recording decision dependencies
The authors propose decision lineage as a recovery approach. It connects source evidence, a generated assertion, the authority granted to that assertion and the decisions that rely on it. Data lineage shows where an assertion traveled; decision lineage also shows what the organization did because it believed the assertion.
Related tools already exist. The World Wide Web Consortium's W3C PROV model describes the entities, activities and agents involved in producing data; OpenLineage standardizes lineage metadata for datasets, jobs and runs; and event sourcing records application-state changes as a sequence of events. According to the authors, practical implementations often stop at dataset and job boundaries, without reaching decision records or the retrieval layer that assembles context for agents.
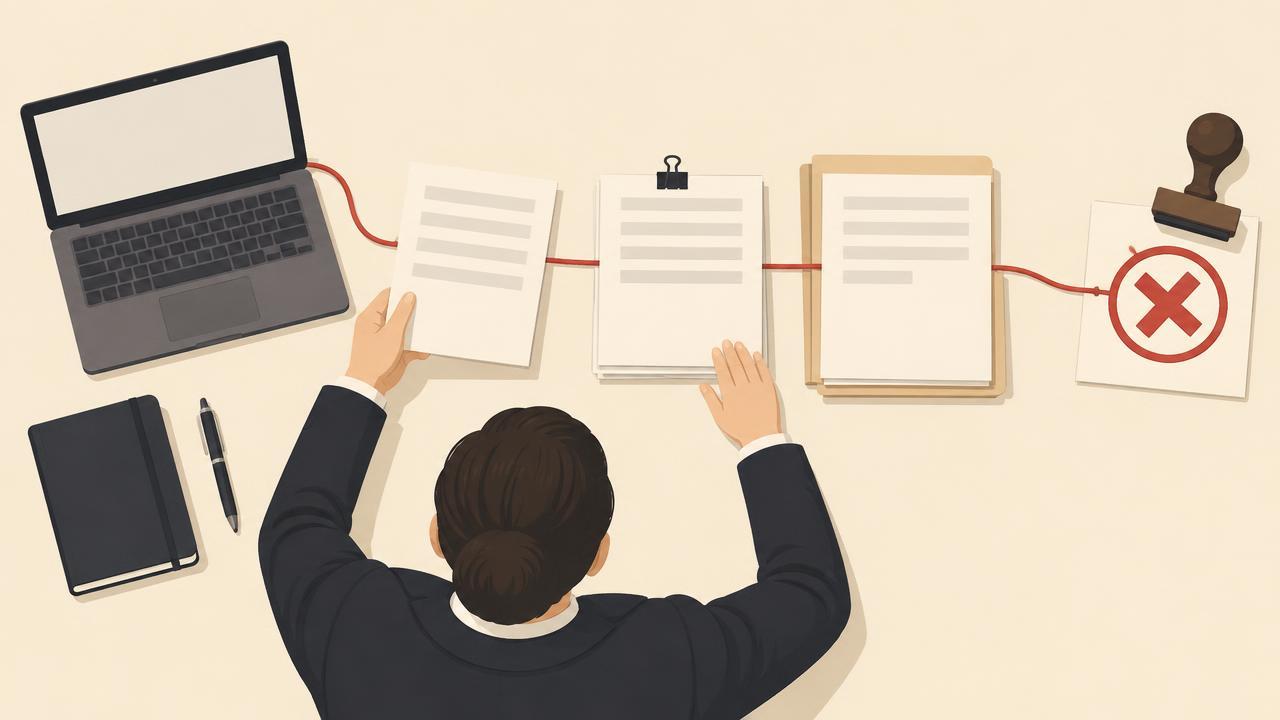
In the supplier example, the traceable chain runs from the certificate through the agent's finding and accepted supplier record to the sourcing decision, then to the dashboard, report and search index. If the finding is withdrawn, those links can identify affected decisions and materials that inherited the stale conclusion.
Some recovery can be automated: systems can remove stale search results, refresh dashboards, flag reports for regeneration, stop pending workflows and open review tasks. The owner of an already-made sourcing decision, however, decides whether it should stand or be reversed and whether customers or regulators need to be notified.
How the pattern can work
The process begins where the agent's output enters the system of record. The agent records a proposal linked to the evidence it reviewed; a deterministic workflow under business ownership decides whether to accept it for a defined use. If a mandatory check cannot run, the finding remains a proposal and must not silently become an accepted fact.
Once accepted, a consequential decision needs a link to the finding and to the particular version of the supporting evidence. A relatively small dependency record can contain the assertion identifier, an evidence snapshot, the approving workflow and permitted use, along with identifiers for affected decisions, dashboards, reports and indexes. The system does not need a universal graph of everything the agent did.
The relationship must remain recognizable in downstream copies. If an agent retrieves the same finding from a supplier record and a report, the retrieval layer should present them as two copies rather than independent evidence. If the assertion has been withdrawn, it should filter or flag both.
The extra work is not worthwhile for every AI output. Ordinary logging may suffice for a low-stakes answer that is not stored or reused as evidence and is cheap to regenerate. Decision lineage can be justified when a finding may affect an approval, payment, safety, compliance or later machine decisions.
The unit of tracking is not every word but a material assertion, such as a claim that a certificate is valid. A long assessment might contain only one or two such claims; tracking them can cost less in storage, privacy exposure and operations than tracing the entire text. Provenance must also be precise: two laboratories' independent validations should not be merged into one source merely because their results agree.
Testing whether a correction traveled far enough
Recording dependencies does not itself prove that a correction reaches every affected system. The authors recommend a controlled test: allow an incorrect finding to reach a report and search index, then withdraw it. The test succeeds only if the affected decision can be found and stale copies stop appearing as current evidence within the recovery time the process requires.
Three indicators can measure the result: the share of consequential decisions traceable to a supporting finding; the time between withdrawal and identification of affected decisions; and the number of withdrawn copies still returned as valid evidence. Targets depend on the process. A payment approval might require affected decisions to be identified within an hour and no stale results, while a review-queue priority might tolerate a day.
If the supplier example is replayed with this pattern, the 11:00 a.m. correction withdraws the finding, sends the supplier back for review, refreshes the dashboard, flags the report for regeneration, removes stale search results and sends the procurement lead a review task. By 2:00 p.m., the dashboard shows the supplier as under review. The original mistake still occurred, but its spread is visible and its consequences can be addressed by the responsible decision-maker.
Decision lineage does not establish that evidence is authentic, replace data-quality or access controls, or guarantee that an AI conclusion is correct. It helps an organization find and reconsider the influence of an accepted assertion when that assertion later changes.